Introducing… The Terminator Pro Max
submitted by /u/ctrl-shift-face [link] [comments]
submitted by /u/ctrl-shift-face [link] [comments]
Large language models (LLMs) exhibit a wide range of human-like behaviors, from expressing thoughts and emotions, to engaging in relationship-building with users, to refusing requests and maintaining boundaries. Despite their prevalence, researchers and practitioners lack methods and empirical insights to make informed decisions about when and what types of human-like behaviors LLMs should exhibit. To …
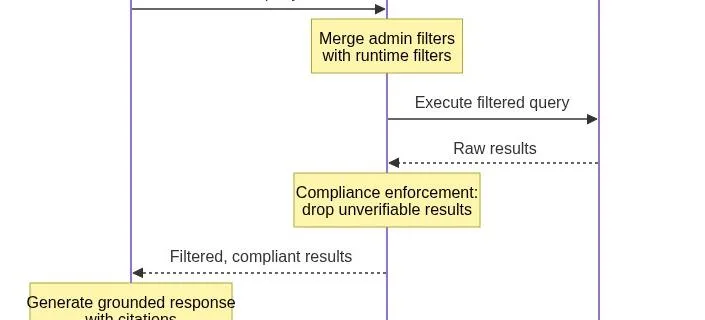
When an AI agent uses Web Search to ground its answers on behalf of a customer, the organization behind that agent needs domain and date filters to control which sources the agent consults and how fresh those sources must be. A financial-services agent shouldn’t ground its answers in an unvetted blog. A product-information agent shouldn’t …
Read more “Domain and publish date filters for Web Search on AgentCore”
Rob Strechay, until recently managing director and principal analyst at theCUBE Research, has joined VentureBeat as our first Lead Analyst and a founding analyst of VentureBeat Research. His arrival is the next step in a deliberate move at VentureBeat toward deeper specialization: analysis built for the technical decision-makers — the directors, VPs, CIOs, and CTOs …
Sources tell WIRED that Elon Musk is expected to spend up to $200 million in the midterms. It could be a big boost for GOP Senate candidate Ken Paxton, who’s struggled to raise cash.
New research published in Proceedings of the National Academy of Sciences suggests that when artificial intelligence (AI) agents interact in groups, their number is not merely a technical detail. It is a decisive factor in what the group settles on: populations built from the same AI model and doing the same task can reach opposite …
Read more “More is different when AI agent populations work together, study suggests”
submitted by /u/ctrl-shift-face [link] [comments]
In this article, you will learn three practical strategies for managing small context windows in large language models, along with working Python examples that demonstrate…
Reinforcement Learning with Verifiable Rewards (RLVR), often optimized with Group Relative Policy Optimization (GRPO), has become a central recipe for improving the reasoning capabilities of pretrained language models but current studies remain heavily English-centric. We conduct a large-scale empirical study of multilingual and non-English GRPO across a wide range of base models, training languages, and …
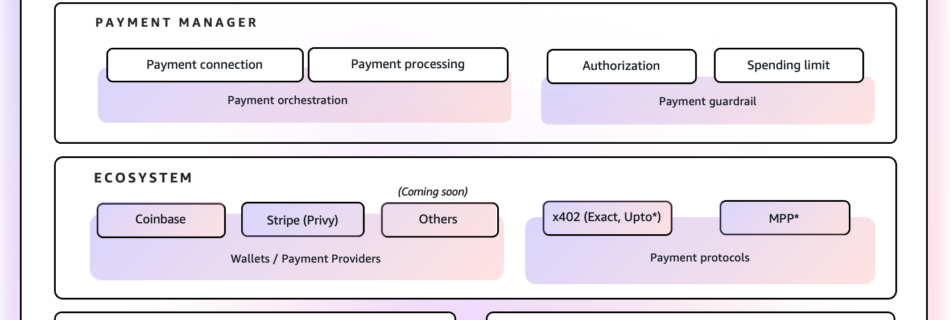
Agents have evolved from simple chat applications to autonomous, long-running systems that dynamically discover and compose dozens of tools per task without human oversight. On the other side, service and content providers are moving from human-centric subscription-based, one-size-fits-all pricing to pay-per-use, per-execution models where costs are often a few cents. Today, agents are doing a …