DiscoSign: Discourse-Aware Text to Sign Language Gloss Translation

Sign language processing systems have traditionally operated at the sentence level, ignoring critical discourse phenomena fundamental to sign language comprehension. We introduce DiscoSign, a computational approach for discourse-aware text to sign language gloss translation grounded in linguistic research. We address three key phenomena within our modular Large Language Model (LLM)-based translation framework: (i) spatial coreference …

ML 20434 1 1

Monitoring production agent lifecycle with AWS DevOps Agent and AgentCore Evaluations

Multi-agent systems in production experience issues in ways that traditional monitoring misses. For example, the agent can’t invoke its foundation model (FM) and returns an empty response. This could be because of a missing AWS Identity and Access Management (IAM) permission on an agent’s execution role that doesn’t throw a 500 error. A supervisor agent …

Tiny nanolaser could cut computer energy use in half

Scientists have created an ultra-small nanolaser that could eventually allow microchips to transmit information with light instead of electricity, potentially making computers faster while cutting energy use roughly in half. Thousands of the lasers could fit on a single chip, opening possibilities for more efficient data centers, smartphones, and advanced medical sensors.

Reminder: Live Today — Building AI Agents, The Loop

Quick note — The Loop’s first session is today, 4:30 PM PDT, live on Zoom. Free, monthly, and genuinely hands-on: what building an AI agent actually looks like, why the internet is shifting from static information to something built for agents and people, and what that shift means for anyone still thinking in old-SEO terms. This is for you …

ML 21885 1

Reduce LLM latency with prefix-aware routing on Amazon SageMaker Inference

When you build an application on top of a large language model (LLM), the prompt you send to the model typically has two parts. There’s a fixed part that sets up context (instructions, reference documents, conversation history) and a variable part that contains the actual user input. Take a customer service bot as an example. …

ML 21725 1

Deploying Qwen3.8-2.4T-A95B on Amazon SageMaker HyperPod with vLLM

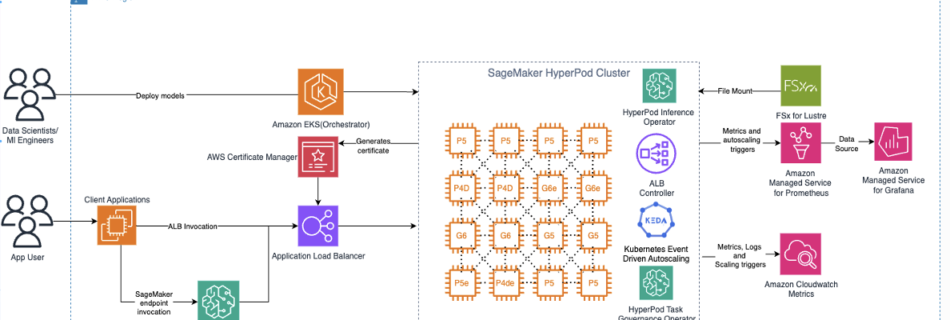
On August 12, 2026, Alibaba’s Qwen team released Qwen3.8-2.4T-A95B. This is the first time a Qwen-Max-class model has been made available as open weights. With 2.4 trillion total parameters (95 billion activated per token), a hybrid linear-plus-full-attention architecture, and native context up to 262K tokens (extensible to 1M), Qwen3.8 targets the most demanding agentic and …