5 Lessons Learned Building RAG Systems
Retrieval augmented generation (RAG) is one of 2025’s hot topics in the AI landscape.
Retrieval augmented generation (RAG) is one of 2025’s hot topics in the AI landscape.
Be sure to check out the previous articles in this series: •
At Apple, we believe privacy is a fundamental human right. And we believe in giving our users a great experience while protecting their privacy. For years, we’ve used techniques like differential privacy as part of our opt-in device analytics program. This lets us gain insights into how our products are used, so we can improve …
Read more “Understanding Aggregate Trends for Apple Intelligence Using Differential Privacy”
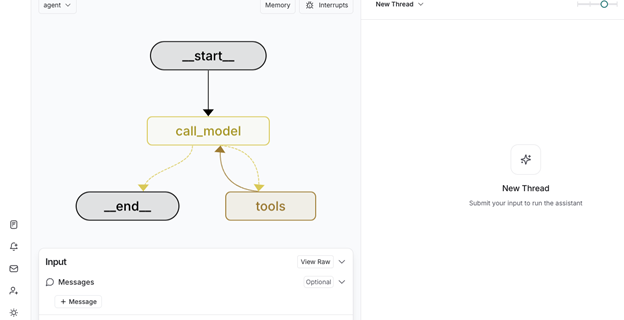
Large language models (LLMs) have raised the bar for human-computer interaction where the expectation from users is that they can communicate with their applications through natural language. Beyond simple language understanding, real-world applications require managing complex workflows, connecting to external data, and coordinating multiple AI capabilities. Imagine scheduling a doctor’s appointment where an AI agent …
Read more “Build multi-agent systems with LangGraph and Amazon Bedrock”
Amex GBT CISO David Levin is accelerating AI security, cutting false positives and speeding SOC response to anticipate and shut down threats.Read More
The abrupt firing of Xiaofeng Wang and his wife from Indiana University last month shocked the academic community and is stoking fears that Chinese-born scholars are being targeted.
A groundbreaking open-source computer program uses artificial intelligence to analyze videos of patients with Parkinson’s disease and other movement disorders. The tool, called VisionMD, helps doctors more accurately monitor subtle motor changes, improving patient care and advancing clinical research.
A small team of AI researchers from Carnegie Mellon University, Stanford University, Harvard University and Princeton University, all in the U.S., has found that if large language models are over-trained, it might make them harder to fine-tune. In their paper posted on the arXiv preprint server, the group compared the impact of different amounts of …
Read more “Over-training large language models may make them harder to fine-tune”
GUEST: Intelligence is pervasive, yet its measurement seems subjective. At best, we approximate its measure through tests and benchmarks. Think of college entrance exams: Every year, countless students sign up, memorize test-prep tricks and sometimes walk away with perfect scores. Does a single number, say a 100%, mean those who got it share the sa…Read …
Read more “Beyond ARC-AGI: GAIA and the search for a real intelligence benchmark”
The blockbuster antitrust case begins Monday. Its outcome could impact how Big Tech companies grow—but the government has a long way to go to prove its case.