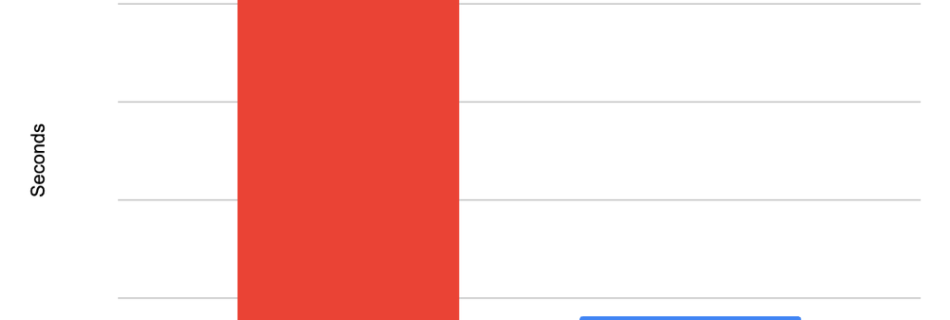
1 5x faster checkpoint restores with Rapidmax 1000x1000 1

Cloud Storage Rapid: Turbocharged object storage for AI and analytics

At Google Cloud Next ’26 we announced Cloud Storage Rapid, a family of object storage capabilities for data-intensive workloads like AI and analytics. Out of the gate, Cloud Storage Rapid consists of Rapid Bucket (formerly Rapid Storage), a high-performance zonal object storage offering, and Rapid Cache (formerly Anywhere Cache), which accelerates reads on-demand and colocates …

People struggle to recall whether content came from AI, with labels forgotten after one week

From August 2026, an EU-wide AI regulation will come into force requiring the labeling of AI-generated content. However, a research team from the University of Bayreuth and Aalto University in Helsinki, Finland, has found that users of AI systems can no longer reliably recall after just one week whether content was generated by AI or …

Its still nuts to me how realistic AI is getting, incredible i can run it on a RTX2060 and get these results. (Z-image-Turbo)

Every image is made with Z-Image-Turbo (See links for loras and prompts) A few of them were ran through z-image-base using the Z-IMAGE upscaling node template on ComfyUI, its very useful and makes images even more detailed and realistic. IMAGE 1: https://civitai.red/images/127883693 IMAGE 2: https://civitai.red/images/129512330 IMAGE 3: https://civitai.red/images/130096740 IMAGE 4: https://civitai.red/images/128214156 IMAGE 5: https://civitai.red/images/130072355 IMAGE …

Flux.2-Klein pipeline for real-time webcam stream processing in 30 FPS

I have built a pipeline based on the Flux.2-Klein-4B model that allows processing of a video stream with low latency (about 0.2 seconds) on a single RTX5090 GPU. It is free and open-source, you can try it locally: https://github.com/tensorforger/FluxRT Under the hood, it uses a custom spatial-aware KV-cache, so it only recomputes a small number …

cover

Adaptive Parallel Reasoning: The Next Paradigm in Efficient Inference Scaling

Overview of adaptive parallel reasoning. What if a reasoning model could decide for itself when to decompose and parallelize independent subtasks, how many concurrent threads to spawn, and how to coordinate them based on the problem at hand? We provide a detailed analysis of recent progress in the field of parallel reasoning, especially Adaptive Parallel …