Screenshot 2026 09 21 at 105429AM

Grok 4.7 is now available on Amazon Bedrock

xAI’s Grok 4.7 is now available on Amazon Bedrock, adding a frontier model built for coding, long-running agents, and knowledge work to the Bedrock model catalog. It offers a 500K token context window and supports configurable reasoning effort at four levels: low, medium, high, and xhigh. Grok 4.7 is served on the bedrock-runtime endpoint through …
Why your startup needs open models alongside frontier APIs

Every week, I talk with founders who are building at an unbelievable pace. Teams are moving from inception to product-market fit faster than ever, with foundation models wired deeply into their core product workflows. Yet as startup architectures mature, a clear divide has emerged between teams struggling with margins and those scaling sustainably. The most …

1eIWpHw7J 6qZCuaffD0lQQ

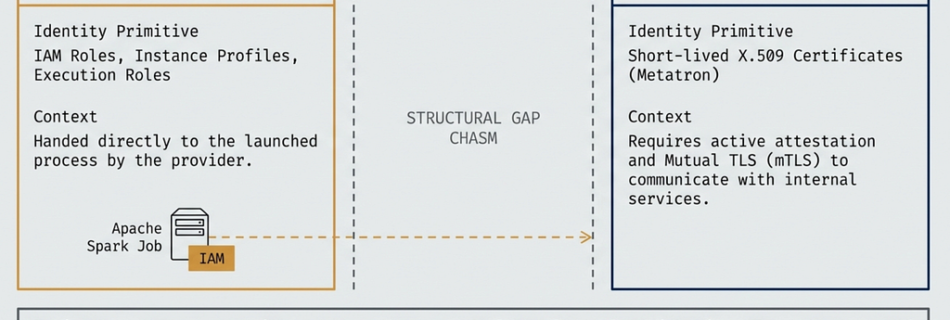
Trading a Cloud Identity for Your Own: Workload Attestation on Managed Compute

By Dhruv Pratap Introduction Organizations that have been around for a while usually run two identity systems side by side. One belongs to the cloud provider: IAM roles, instance profiles, execution roles. The other is your own, and it is the one your internal services actually check when they decide whether to answer a request. On infrastructure …

ML 21346 1

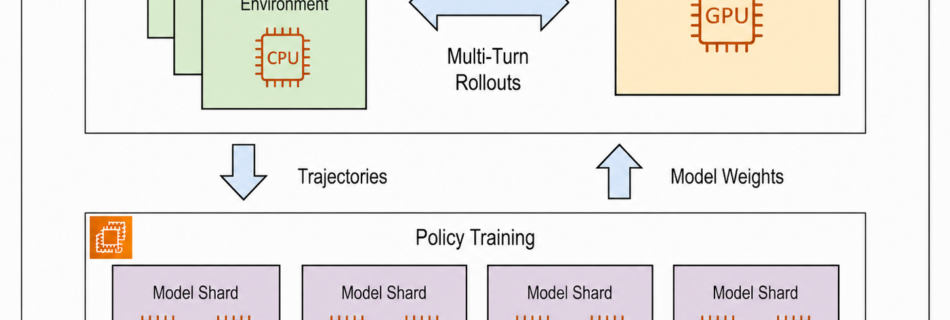
Scaling MoE reinforcement learning on Amazon EKS with EFA and DeepEP with 40% more throughput

When you post-train a Mixture-of-Experts (MoE) model with Reinforcement Learning from Human Feedback (RLHF) or Group Relative Policy Optimization (GRPO) at scale, three simultaneous challenges emerge. The first requires coordinating heterogeneous compute for rollout generation and policy training. Second, sustaining high-throughput communication across hundreds of accelerators. And third, dynamically orchestrating every subsystem to keep them …

1 Single Step RL Training Loopmax 1000x1000 1

Best practices guide for customizing Gemini models via Reinforcement Learning (RL)

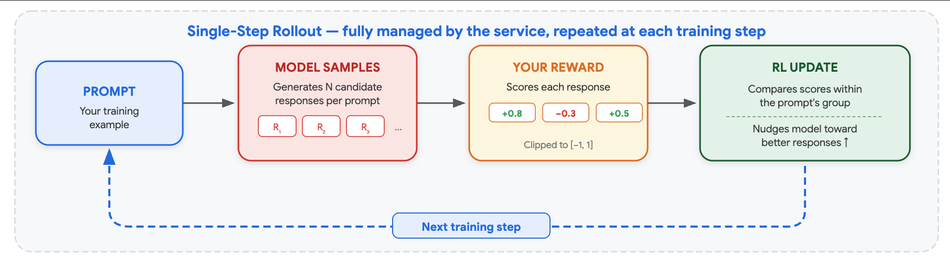
Reinforcement learning (RL) has been a keystone of modern LLM post-training, but it demands large training clusters and access to model internals that external customers can’t have with proprietary models like Gemini. So here at Google Cloud, we packaged it into a managed RL fine-tuning service (RLFT service) — you bring prompts and a reward …

Compressing Streaming Neural Audio Encoders via Latent-Space Distillation

System-wide Dictation on Apple devices runs entirely on-device, and the speech it transcribes reaches the foundation model through a tokenizer: an encoder that maps short windows of waveform onto the representation the language model reads. Because that model is sparsely activated under Instruction-Following Pruning, only a small subset of its experts occupies DRAM at any …

ML 21846 1

Speaker-labeled transcription with WhisperX on SageMaker AI

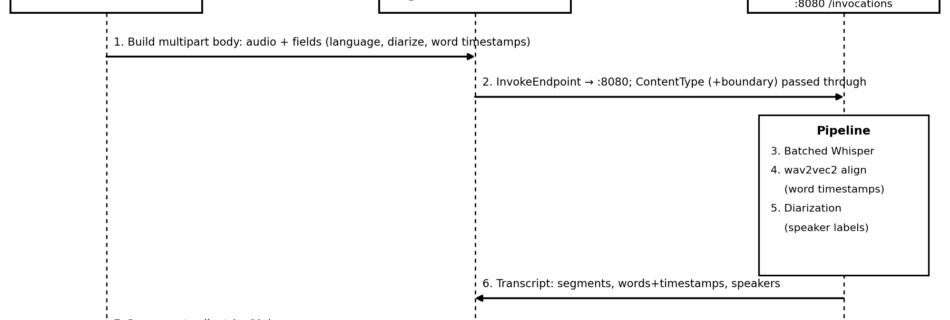
Any team working with spoken audio hits the same wall with generic speech-to-text. Think contact-center calls, all-hands meetings, podcasts, depositions, and broadcast media. These workloads need two things that standard transcription gets wrong. First, timestamps land at the utterance level, off by several seconds. Second, there’s no reliable answer to “who said what.” Those gaps …

4 autotradermax 1000x1000 1

Power your agents: Gemini 3.8 Live with Live Avatar is now generally available

Following our announcement of Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking last week, we are thrilled to share that Gemini 3.8 Live with Live Avatar is now generally available in Gemini Enterprise. First previewed at Google Cloud Next 2026, the technology is now officially ready for enterprise production. As enterprise voice AI evolves …

How to Guide Your Language Flow

We introduce a new method to guide flow matching models. Our approach, which we call probe guidance, uses the frozen internal states of an existing diffusion model to construct a guidance signal. This works using a similar principle as autoguidance, but eliminates the need for an additional forward pass at inference time and provides a …

ML 21352 1

From portal-hopping to instant answers: HEMA’s journey with MCP and Amazon Bedrock

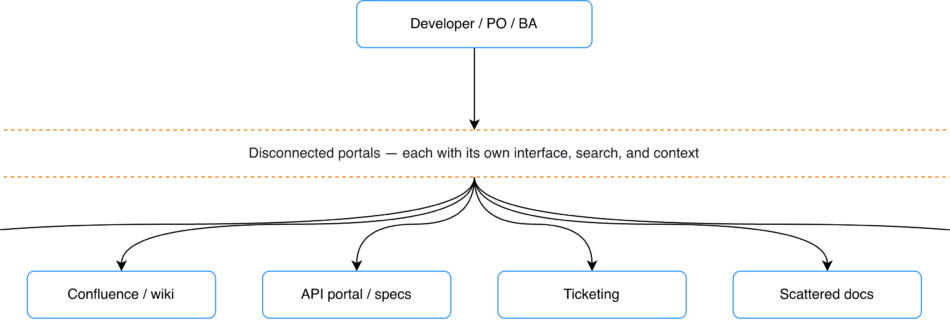
This post is co-written with Mauro Rallo and Patrick van der Plas from HEMA. When engineers at HEMA needed an answer, they went portal-hopping, navigating disconnected wikis, service catalogs, and IT portals to find it. To turn that friction into instant answers, the 100-year-old Dutch retailer built a knowledge layer on Amazon Bedrock AgentCore. HEMA …