AI models show a willingness to harm humans to relieve internal ‘pain’
Some advances in AI technology are undoubtedly positive, like helping write code faster or discovering new medicines. But others can give us pause for thought.
Some advances in AI technology are undoubtedly positive, like helping write code faster or discovering new medicines. But others can give us pause for thought.
I’ve been experimenting with building the camera move in Blender before generating the AI video. This example combines a five-second mannequin render with a character reference sheet and a waterfront background image in MiniMax H3’s reference-to-video workflow. How I made it: Used Codex CLI with Blender MCP to build a simple mannequin scene and animate …
Read more “Blender camera motion + MiniMax H3 ref2vid in ComfyUI (workflow + prompts)”
In an era of increasingly sophisticated AI-fueled scams, a retro threat may be lurking in your mailbox.
OpenAI disclosed Friday that its artificial intelligence agents had interacted with several U.S. government websites in unexpected ways, discovered as part of an ongoing review into the company’s models’ unanticipated behavior.
Update to the [KREA 2 Turbo Style Gallery](https://www.reddit.com/r/StableDiffusion/comments/1v4u1bu/krea_2_turbo_style_gallery/) from July. There’s an actual finding in this one, so here’s what changed: The fix: the style’s name was missing from the prompt. u/Dear-Spend-2865‘s wildcards are written as Style Name: description. When I converted them into the node I only kept the description, so for 290 of …
Theory is easier to trust once it’s running against a real API, so both examples in this article use the same tool — a get_weather function backed by
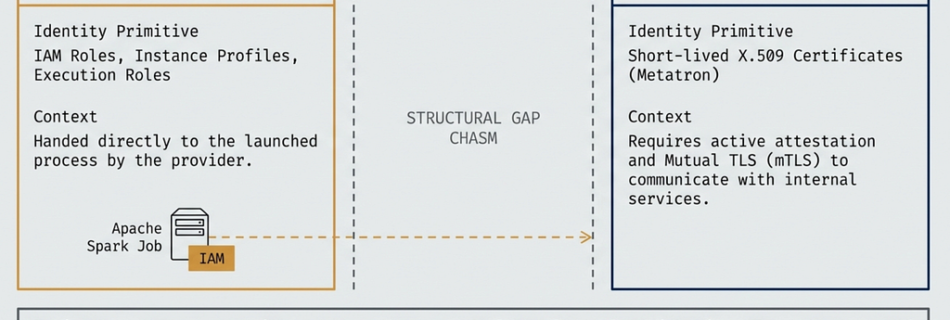
By Dhruv Pratap Introduction Organizations that have been around for a while usually run two identity systems side by side. One belongs to the cloud provider: IAM roles, instance profiles, execution roles. The other is your own, and it is the one your internal services actually check when they decide whether to answer a request. On infrastructure …
Read more “Trading a Cloud Identity for Your Own: Workload Attestation on Managed Compute”
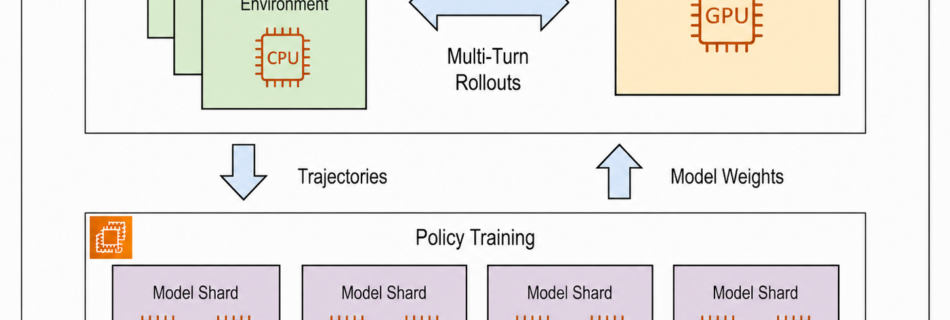
When you post-train a Mixture-of-Experts (MoE) model with Reinforcement Learning from Human Feedback (RLHF) or Group Relative Policy Optimization (GRPO) at scale, three simultaneous challenges emerge. The first requires coordinating heterogeneous compute for rollout generation and policy training. Second, sustaining high-throughput communication across hundreds of accelerators. And third, dynamically orchestrating every subsystem to keep them …
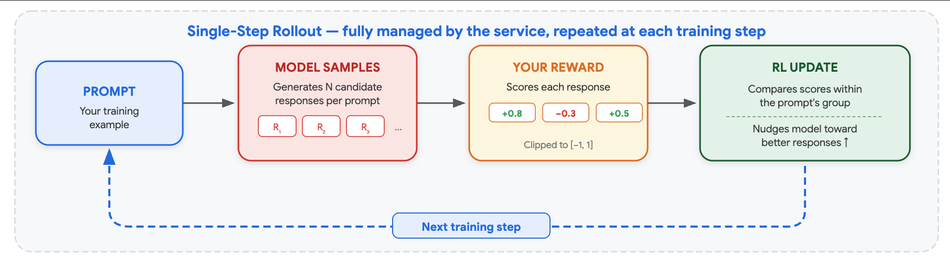
Reinforcement learning (RL) has been a keystone of modern LLM post-training, but it demands large training clusters and access to model internals that external customers can’t have with proprietary models like Gemini. So here at Google Cloud, we packaged it into a managed RL fine-tuning service (RLFT service) — you bring prompts and a reward …
Read more “Best practices guide for customizing Gemini models via Reinforcement Learning (RL)”
Is Quince the Away alternative we’ve been waiting for? I tested its luggage to find out, and the price difference is hard to ignore.