ML 22216 1 1

SageMaker Inference now supports Multi-Instance GPU to maximize GPU utilization for model endpoints

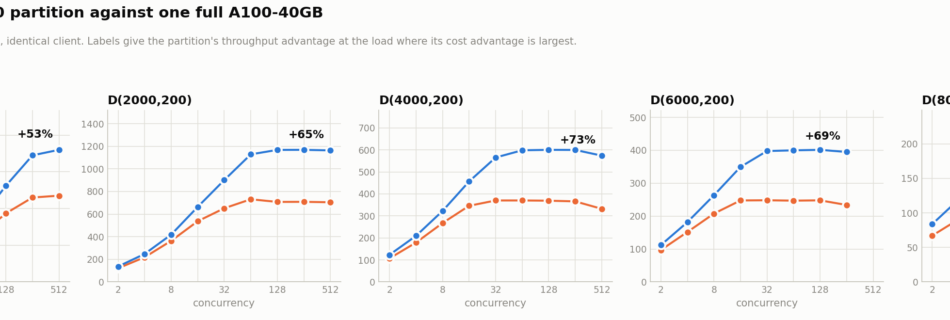
When you deploy a model to a GPU endpoint, the smallest unit of GPU you can request is one whole accelerator. This constraint can cost you twice. First, you can’t host more models on an instance than it has accelerators. An ml.p4d.24xlarge has eight A100s, so it holds eight models, whether each one needs 40 …
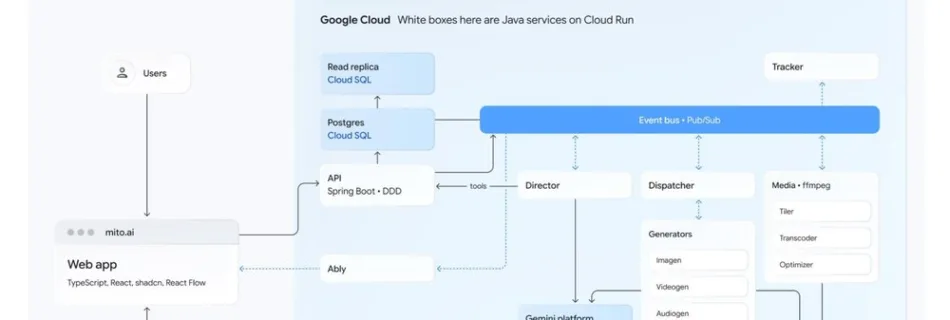
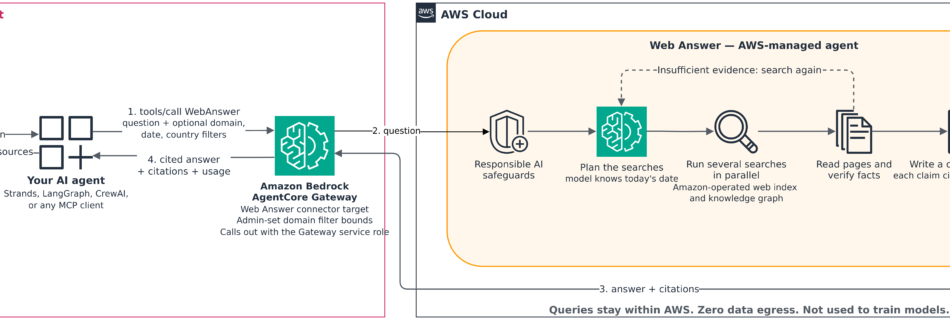
image2 VoY9Mlsmax 1000x1000 1

The Blueprint: Orchestrating 5,000+ AI assets for a World Cup TV spot

Welcome back to The Blueprint, a regular feature where we highlight how Google Cloud customers are tackling unique and common challenges across industries using the latest AI and cloud technologies. We hope to inspire others looking to innovate in their work. AI is rapidly transforming video production at virtually every step of the process, from …

Minimax H3 character swap is 🤌

Just goofing around with the stock ref2vid workflow, character swap Lora, and some character sheets. Did all of the shots separately and reassembled in my NLE. Almost all of the clips were first attempts. I was floored by how well it tracked the guys without any masking. submitted by /u/tindell- [link] [comments]

Faster Retrieval for Better, More Efficient RAG

Maximum inner product search (MIPS) sits at the core of recommendation systems, search, and retrieval-augmented generation (RAG). Given a query vector, MIPS systems search within a database of millions of candidate key vectors for the one that best matches the query. The original data point associated with that best-matching key is then used to handle …

ML 22248 1

Getting started with Web Answer on Amazon Bedrock AgentCore

Today, we are announcing the general availability of Web Answer on Amazon Bedrock AgentCore. With Web Answer, agent builders get a synthesized, source-cited answer to a natural-language question with a single tool call. They no longer build a search, retrieve, synthesize, and citation pipeline themselves. If you have built agents that need to answer questions …

artlistmax 1000x1000 1

Gemini Omni 1.2 Flash: Fast, cost-effective, and reliable video generation and editing now generally available

Today, Gemini Omni 1.2 Flash is generally available on Google Cloud. Built for the everyday videos businesses make in volume — like product videos, virtual try-ons, and ads — this model is fast, cost-effective, and follows your image, video and audio references more closely than before.   Business users can create with it in Gemini for …